

The developer's guide to AI tools that actually save time
The article cuts through AI hype to highlight tools that genuinely boost developer productivity by augmenting skills and handling repetitive tasks. It emphasizes a strategic approach rather than expecting full automation…
→ View original source
How Profitable is LLM Inference? Doing the Math on Kimi K3
The article examines the economic viability of LLM inference for Kimi K3, analyzing factors like batch size and GPU utilization to determine cost-effective token pricing. It applies simplified mathematical models to esti…
→ View original source
Anthropic is finding bugs faster than Microsoft can fix them
Anthropic's security researchers are discovering software vulnerabilities at a rate exceeding Microsoft's patching capacity, forcing the tech giant into an accelerated remediation cycle. Microsoft is reportedly racing to…
→ View original source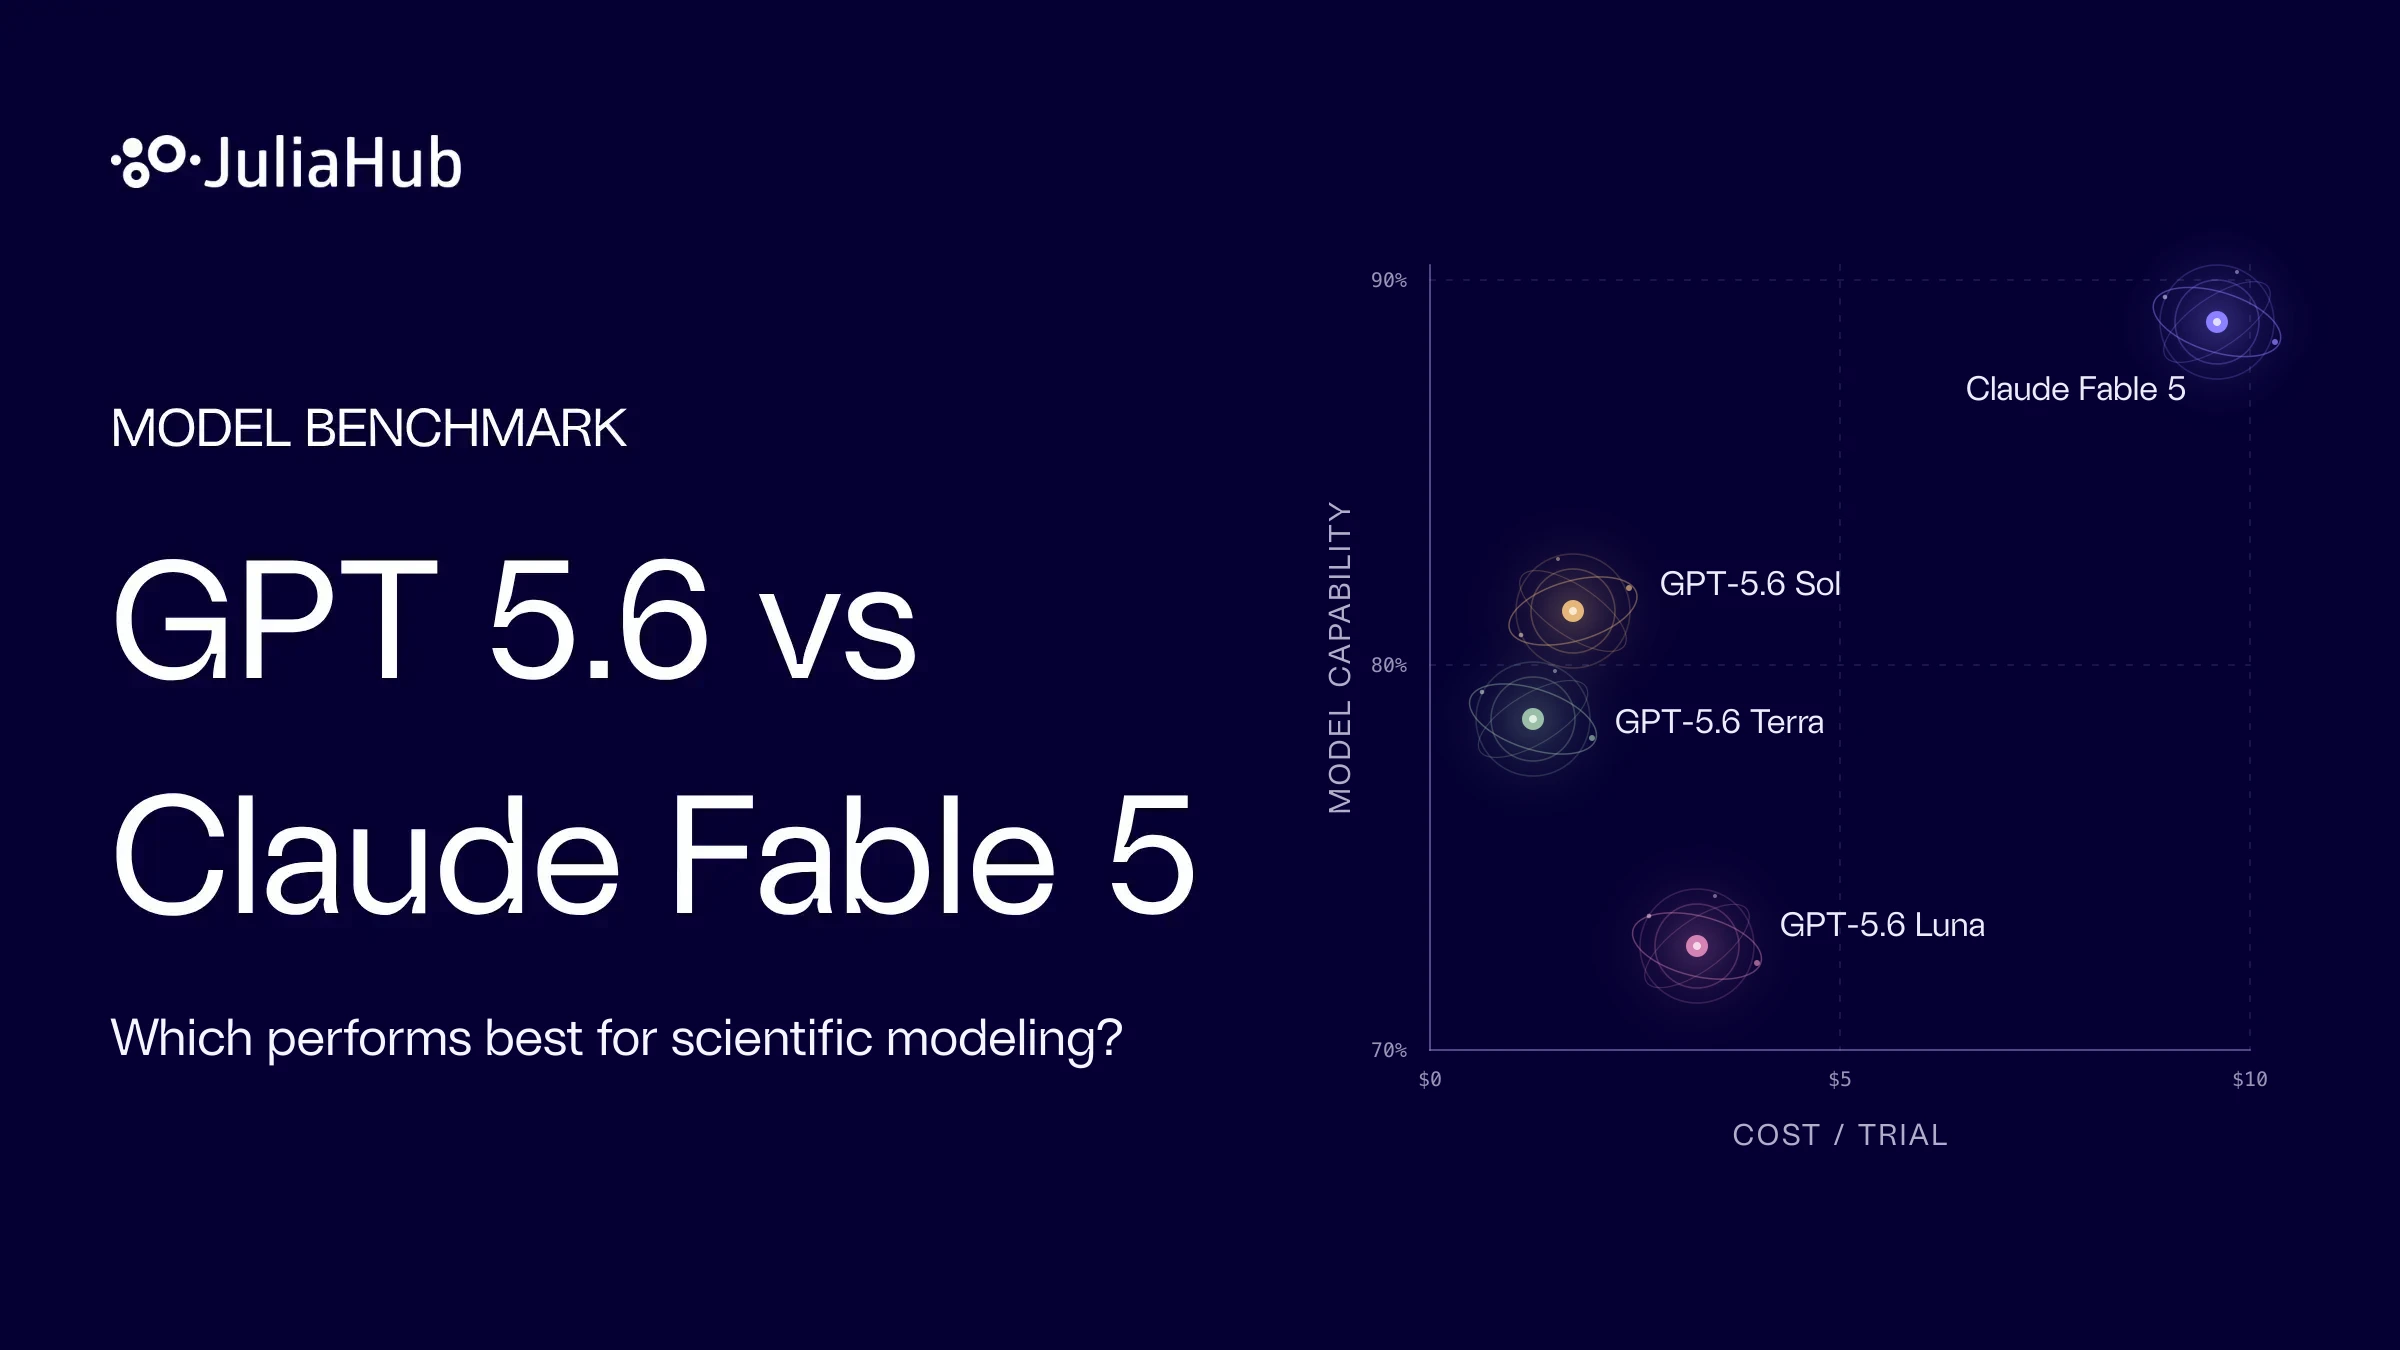
GPT-5.6 vs. Claude Fable 5 for Physical AI, which performs best?
A comparative evaluation of GPT-5.6 and Claude Fable 5 was conducted for Physical AI applications, assessing their performance in tasks requiring real-world reasoning and interaction. The analysis, published on Hacker Ne…
→ View original source
Claude: Elevated errors across all models – Resolved
An incident on 2026-07-29 reported elevated error rates affecting all Claude models. The issue was investigated and resolved, restoring normal operation across the platform. Read original
→ View original source
SpecFirst: Behavioral Specification Elicitation as a First-Class Step in Agent-Based Program Synthesis from Scratch
LLM-based agents excel at software engineering tasks where an existing codebase provides context, but constructing a program from scratch remains fundamentally harder. Recent benchmarks such as Progra
→ View original source
OmegaUse-OfficeVal: Benchmarking LLM Agents on Long-Horizon Office-Suite Tasks with Economic Grounding
OmegaUse-OfficeVal is a new benchmark designed to evaluate Large Language Model (LLM) agents performing long-horizon office-suite tasks. The framework introduces task-level economic grounding to assess whether agents can…
→ View original source
SecRespond: Benchmarking AI Agents for Real-World Post-Compromise Incident Response
Large Language Model (LLM) agents are increasingly adopted in real-world security operations with access to host artifacts and command-line interfaces (CLIs), making it critical to thoroughly assess t
→ View original source
TurboVLA: Real-Time Vision-Language-Action Model at 32 Hz on an RTX 4090 with <1 GB VRAM
Vision-language-action (VLA) models commonly adopt an LLM-centric V to L to A pathway, where visual observations are projected into the representation space of a large language model before being deco
→ View original sourcemicrosoft /agent-governance-toolkit
The Microsoft Agent Governance Toolkit provides a comprehensive framework for securing autonomous AI agents, implementing policy enforcement, zero‑trust identity, execution sandboxing, and reliability engineering. It add…
→ View original sourceShow HN: Open-source engine running Gemma 4 26B in 2 GB RAM on any M-series Mac
An open-source engine called Turbo Fieldfare enables running Gemma 4 26B on M-series Macs with just 2 GB of RAM. Developed by drumih, the project demonstrates efficient model optimization techniques for consumer hardware…
→ View original source